Which filtered page deserves a place in search? Start with search intent, a relevant product selection and distinct value. This guide separates indexable facets from sorting states and arbitrary combinations, then explains the appropriate technical controls.
This article is an in-depth expert contribution from our content cluster. Discover the complete overview on our main page: SEO & Content →
The Era of Agentic Search Engines & AI Scrapers
For SEO faceted navigation, start with a concrete decision: should shoppers find this filtered product list through search? Google recommends allowing crawling for needed facet URLs and preventing unnecessary combinations from consuming crawling resources. Use the decision checklist below to build an explicit allowlist for your store.
- Halt the Combinatorial Explosion: Freely combinable filters generate many similar URLs. An explicit allowlist limits which of them search engines should discover.
- Architectural Separation of Content vs. State: SEO-valuable facet combinations (e.g., Brand + Color) receive permanent Clean URLs. Handle sorting and arbitrary combinations separately: canonical for duplicates, noindex for index exclusion and robots.txt for crawl control.
- Shielding Crawl Budget: Indexing and crawling are separate tasks. A URL blocked by robots.txt cannot deliver its noindex signal to Google.
- 1. SEO Faceted Navigation: The Indexing Decision
- 2. The Core Problem: Crawl Budget Waste & Duplicate Content
- 3. Technical Solutions for Filter Management
- 3.1 Facet Decision Matrix for SEO
- 3.2 Platform Execution: Shopware 6, Shopify & WooCommerce
- 4. The PRG Pattern: Filter Interaction and URL Control
- 5. Link Attributes & Dofollow/Nofollow Strategies
- 6. Roadmap: Shop Audit & Implementation
- 7. Best Practices for URL Structure in E-Commerce
- 8. Frequently Asked Questions (Glossary)
1. SEO Faceted Navigation: The Indexing Decision
To succeed and scale profitably in modern e-commerce, delivering a frictionless, instant User Experience (UX) is non-negotiable. A cornerstone of this shopping experience is faceted navigation (often called multi-attribute filtering). Online shoppers expect to effortlessly narrow down catalogs of tens of thousands of products by color, size, brand, material, price range, or instant availability within milliseconds. From a conversion rate optimization standpoint, this filtering capability is essential.
Uncontrolled filters can create very large URL spaces through combinatorial explosion. Similar product lists consume crawling resources and can delay discovery of new products. Google describes this in its faceted navigation documentation; this does not imply automatic de-indexing of existing products.
Solving this dilemma requires an architectural separation between frontend usability and indexing hierarchy. Enterprise-grade stores rely on four foundational pillars:
1. Clean Slugs for Search Demand
High-demand filter combinations (e.g., Category + Brand or Main Color) are rendered as dedicated, crawlable Clean URLs with distinct content, optimized H1 headings, and self-referencing canonicals.
2. Bot Governance & Scraper Shielding
Control transient and combinatorial filters according to their search value; keep approved search destinations discoverable.
3. Canonicalization Logic
A rigorous matrix of Canonical tags and server-side parameter normalization ensures identical product sets under varying query orders are consolidated.
4. Virtual PRG & Client State
Adopting modern standards like the Post-Redirect-Get (PRG) pattern or client-side History API manipulation to execute filter clicks without exposing crawler links.
2. The Core Problem: Crawl Budget Waste & Duplicate Content
What is Crawl Budget and Why is it Finite?
The Crawl Budget is the total volume of URLs a search engine crawler (such as Googlebot, Bingbot, or Applebot) can and intends to fetch on your domain within a specific timeframe. This budget is determined dynamically by two core factors:
When an e-commerce platform generates millions of Parameterized URL combinations (such as ?color=blue&size=44&price_min=50&sort=rating_desc), bots squander their crawling limits parsing marginally altered product listings. The crawl budget is depleted before crawlers ever discover your highest-margin product pages or newly launched collections.
Spider Traps and the Combinatorial Explosion
A Spider Trap occurs when dynamic scripts or filter mechanisms generate an infinite chain of unique URLs that web crawlers follow endlessly. Common culprits in e-commerce include:
- Varying Parameter Orders:
/shoes?color=red&size=42vs./shoes?size=42&color=red(duplicate pages under different URLs). - Multi-Select Attributes:
/shoes?color=red,blue,green,yellow,black. - Combining Filters with Sorting & Pagination:
/category?sort=price_asc&page=7&limit=48&view=grid. - Session IDs and Tracking Parameters embedded in internal navigation.
The Hidden Cost Trap: AI Scrapers & Server Crashes
Unnecessary filter requests put load on the web server and database. Check actual requests and response times in your logs before defining crawl rules or access limits.
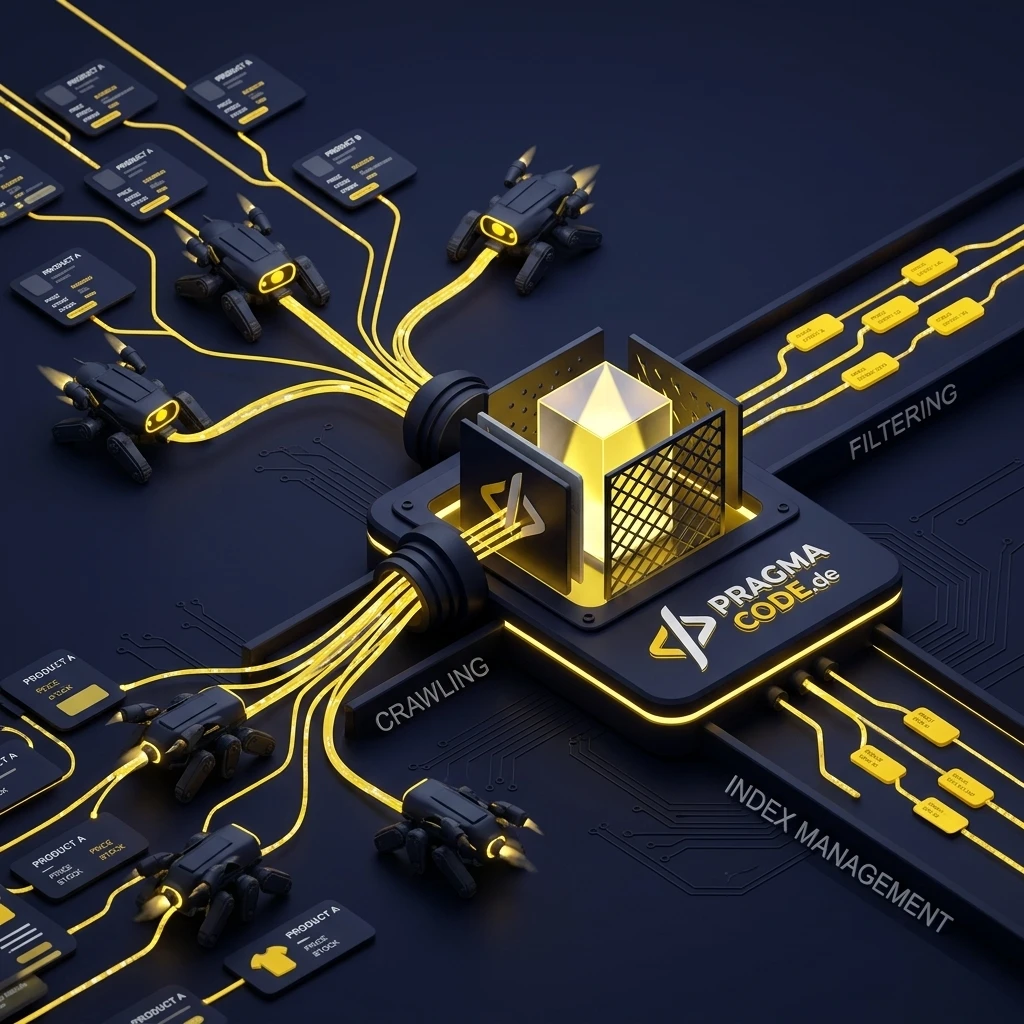
The Problem: Uncontrolled Filter URLs
A shop without technical SEO for filters generates URLs exponentially.
Crawling without clear search valueRepeated crawling of similar parameter URLs consumes resources that could serve useful product pages.
The Ideal Case: Clean Index
A shop with strict index management and PRG pattern.
Explicitly approved URLsPrioritize useful categories, selected filter landing pages and products; monitor their discovery and indexing in Search Console.
3. Technical Solutions for Filter Management
To control faceted navigation, web engineering provides multiple proven levers. No single tool is a universal silver bullet – success lies in their orchestrated implementation.
Comparison: Technical Mechanisms for Faceted Filtering
- Rel="canonical": Signals the preferred URL for duplicate or very similar content. May reduce crawling over time, but is not a crawl block.
- Meta Robots "noindex, follow": Excludes a page from the index when Google can crawl the signal. Also link important products from indexable categories.
- Robots.txt Disallow: Prevents Googlebot crawling but does not guarantee index exclusion. Products must remain discoverable through allowed pages.
- PRG Pattern (Post-Redirect-Get): Form-based filtering without a regular anchor link; the resulting GET URL still needs separate controls.
- Virtual PRG (Client State): Filter execution via JavaScript state and
<button>elements without crawlablehrefpaths. - Edge Canonicalization: Cloudflare Workers or Varnish sanitize parameter chains at the CDN edge prior to hitting origin servers.
When to Use Canonical vs. Noindex vs. Disallow?
The choice of directive depends entirely on the commercial and search intent value of each filter permutation:
Filter combinations with established search volume (e.g., "Women's Running Shoes Waterproof" or "White Nike Sneakers") are converted into indexable Clean URLs. They feature self-referencing Canonical Tag elements, tailored metadata, and optimized H1 headers. Which facets genuinely have that demand is settled by a keyword analysis for online shops before the rebuild.
Sorting states and arbitrary combinations without distinct search value should not become separate search destinations. Treat category pagination separately: Google recommends distinct URLs and self-canonicals for subsequent pages so additional products remain discoverable.
Limit unnecessary filter patterns using an explicit allowlist. The number of selected facets alone does not determine search value. Already indexed URLs must initially remain crawlable to deliver a noindex signal.
Example of Index Exclusion in the HTML Head:
<head>
  <!-- Example URL: /catalog/sneakers?color=red&sort=price_asc -->
  <!-- Index exclusion: this URL must remain crawlable -->
  <meta name="robots" content="noindex, follow" />
</head>
3.1 Faceted Navigation SEO: Which Filter Pages Should Index?
Use this decision checklist before implementation. The URL patterns below are illustrative examples, not blanket indexing rules.
- Approve for indexing: Does the combination serve demonstrated search intent, provide a sufficiently stable and relevant product selection, and add value beyond the parent category? Give it a permanent, internally linked URL with a matching title, H1 and self-canonical.
- Do not approve as a search destination: Without distinct value or demand, do not create another SEO landing page. For already indexed combinations use a crawlable
noindex; for unnecessary crawl spaces consider targeted robots.txt rules. - Check exceptions: Consolidate duplicate or very similar lists with canonical. Return
404for empty or nonsensical combinations as described in Google’s guide; treat pagination separately.
Google’s facet guide covers crawl controls and empty results. Google must be able to fetch noindex; canonical consolidates similar content.
| Filter Dimension | URL Pattern Example | Technical SEO Setup | Indexation State | Architectural Rationale |
|---|---|---|---|---|
| Category + Primary Brand | /running-shoes/nike |
If approved: stable URL + self-canonical | Indexable if approved | Approve only with demonstrated demand and a relevant product selection. |
| Category + Brand + Color | /running-shoes/nike/black |
If approved: stable URL + self-canonical | Indexable if approved | Check distinct search intent; do not automatically index every color. |
| Sorting (Price, Newest) | ?sort=price_asc |
Canonical for duplicate or very similar lists | Not Indexed | Re-orders identical products without adding informational value; pure duplicate content. |
| Price Ranges & Sliders | ?price_min=50&price_max=120 |
Virtual PRG or noindex, follow |
Not Indexed | Limit arbitrary slider values; assess curated price destinations separately. |
| Sizes & Multi-Attributes | ?size=42,43,44 |
For existing URLs: crawlable noindex |
Not Indexed | Limit multi-selection; a searched single size may deserve its own destination. |
| Pagination (Page 2+) | ?p=2 or /page-2 |
Self-Canonical (never canonicalize to page 1!) | Indexable | Subsequent page items must remain crawlable and discoverable by Googlebot. |
| Unapproved Combinations | ?brand=nike&color=red&size=42&mat=mesh |
Robots.txt Disallow & Edge Blocking | Blocked | Block crawling after checking existing indexation; no blanket dimension limit. |
3.2 Faceted Navigation SEO in Shopware 6, Shopify & WooCommerce
Implementing this framework varies considerably across major e-commerce platforms:
Shopware 6: Property Mapping & Sales Channel Canonicalization
Shopware 6 boasts a clean underlying schema but defaults to parameter URLs (?properties=...) for active filters. Best practice: Map high-volume search properties into dedicated Dynamic Product Groups with clean SEO slugs. For secondary UX filters, employ Virtual PRG patterns via customized Twig templates to prevent link injection into the DOM.
WooCommerce: Permalink Rewriting & Parameter Pruning
Native WooCommerce generates messy filter URLs like /category/?filter_color=blue using standard anchor tags. Recommendation: Migrate to headless architectures or AJAX-based facet systems that process clicks as state updates without publishing crawlable hyperlinks. Canonicalize only duplicate or very similar lists to the category; approved search destinations retain their own canonical URL.
Shopify: Collection Tag Governance & Liquid Canonical Overrides
Shopify's tagged collections (/collections/category/filter-tag) frequently induce index bloat when multi-tag combinations index unchecked. Check the theme’s canonical output against the allowlist instead of pointing every combination to the root collection.
4. The PRG Pattern: Filter Interaction and URL Control
The PRG Pattern (Post-Redirect-Get) separates form submission from result retrieval. An absent anchor link is not an indexing block: the resulting GET URL may be discovered through other links. Google documents crawlable links; destination URLs still require deliberate crawling and indexing controls.
How the Classic PRG Pattern Works in SEO
Instead of standard anchor links (<a href="...">) that search engine crawlers automatically parse, filter options are submitted as lightweight HTML forms using the POST method:
POST Request on Filter Click
The filter click submits the selection via POST instead of a regular <a href> link. This removes that direct crawl link; the later result URL still requires separate assessment.
302 / 303 Server Redirect
The server processes the selected filter parameters, calculates the destination URL, and responds with an HTTP Status Code 303 (See Other) or 302 Redirect pointing to the filtered URL.
GET Request & Product Display
The user's browser follows the redirect and loads the filtered catalog via standard GET request. The shopper gets the filtered view with a shareable URL, whose discovery and indexability must be controlled separately.
Expert Tip: Virtual PRG in Headless & Modern Jamstack Shops
In modern headless frontends (e.g., built with Next.js, Remix, or Astro), the PRG pattern is frequently executed via Virtual PRG: filter items are rendered semantically as <button type="button">. On click, the product grid updates asynchronously via GraphQL/REST while the URL is updated with window.history.replaceState(). Since Googlebot does not click buttons lacking href attributes, that direct link path is absent. A parameter URL set through the History API does not automatically become uncrawlable.
5. Link Attributes & Dofollow/Nofollow Strategies
When a complete architectural migration to the PRG pattern is not immediately feasible, developers frequently leverage HTML link attributes like rel="nofollow" to guide crawler navigation.
rel="nofollow"
The Filter Blocker
Appended to filter links crawlers should ignore (e.g., sorting orders or multi-attribute combinations).
no rel attribute (default)
SEO Landing Pages
Reserved exclusively for curated Clean URLs intended to rank in search results (e.g., "Red Shoes").
Nofollow is not a crawl block: Use normal links without nofollow for approved search destinations; no special dofollow attribute is needed. Google explains link attributes. Use targeted robots.txt rules rather than relying solely on nofollow hints for unwanted facets.
6. Roadmap: Shop Audit & Implementation
How do you methodically transform an existing e-commerce store with acute indexing issues into a high-performance, SEO-resilient platform? Follow this battle-tested 4-phase roadmap:
Logfile Analysis & Bot Audit
Analyze a representative period of web server logs. Identify filter patterns bots fetch frequently and check whether discovery of important products is delayed. Set priorities from the actual store rather than an arbitrary percentage threshold.
Potential Mapping: SEO Facets vs. UX Filters
Conduct detailed keyword mapping. Which filter combinations show meaningful search demand (e.g., Brand + Category, Material + Category)? Designate these as crawlable Clean URLs, while marking all other permutations for exclusion.
Technical Implementation (PRG & Edge Rules)
Refactor frontend filter UI to Virtual PRG or form POSTs. Configure strict Disallow patterns in robots.txt for low-value parameters and deploy self-referencing canonicals on authorized Clean URLs.
Monitoring via Google Search Console
Track the "Page Indexing" report in Google Search Console. Verify that "Crawled - currently not indexed" counts decrease while crawl frequency and indexing speed on primary product detail pages improve significantly.
7. Best Practices for URL Structure in E-Commerce
Your URL structure is the bedrock of your store's information architecture. Avoid cryptic parameter strings in favor of an intuitive separation between content entities and user states:
https://www.shop.com/catalog?category=123&brand=nike&color=red&sort=price_asc
Incomprehensible to users and bots; induces duplicate content and crawl budget loss.
https://www.shop.com/shoes/nike/red
Fully indexable, semantically clear, optimized for targeted long-tail search demand.
https://www.shop.com/shoes/nike/red?sort=price_asc&size=42
Clean URL for SEO dimensions; volatile UX filters execute via Virtual PRG or carry strict noindex.
Quick-Check: Your Path to Index Management Excellence
Have Questions About E-Commerce SEO & Shop Architecture?
Schedule your free consultation8. Frequently Asked Questions (Glossary)
What is Faceted Navigation?
Faceted Navigation is a user interface pattern enabling users to narrow down catalog results by simultaneously applying multiple attribute filters like color, size, price, or brand. Essential for e-commerce UX, but hazardous for SEO.
What is Crawl Budget?
Crawl Budget represents the number of URLs a search engine bot (like Googlebot) can and intends to fetch across a domain within a given timeframe, governed by crawl capacity and crawl demand.
What is the Canonical Tag?
The Canonical Tag (rel="canonical") is a signal in the page head indicating the preferred URL for duplicate or very similar content. It does not force selection of that URL or exclusion of other variants from the index.
What is the PRG Pattern?
The Post-Redirect-Get (PRG) Pattern is an architectural web pattern. In SEO, it dispatches filter requests via form POSTs redirecting to GET URLs. The resulting GET URLs can still be discovered through other links and need their own crawling and indexing rules.
What is a Spider Trap?
A Spider Trap is a structural website defect that traps web crawlers in an infinite loop of dynamically generated URLs, depleting crawl budget rapidly.
What is User Experience (UX)?
User Experience encompasses every facet of a shopper's perception and interaction with an online store, from instant filtering speed to frictionless navigation and checkout.
<div class="glossary-item">
    <h3>Which filter pages should faceted navigation SEO make indexable?</h3>
    <p>Approve filter pages with demonstrated search intent, a relevant stable product selection and distinct value beyond the parent category. Use a permanent, internally linked URL with matching metadata and a self-canonical. Sorting states and arbitrary combinations without that value are not separate search destinations.</p>
</div>

<div class="glossary-item">
    <h3>Should you use canonical tags or noindex for faceted navigation?</h3>
    <p><a href="https://developers.google.com/search/docs/crawling-indexing/consolidate-duplicate-urls" target="_blank" rel="noopener noreferrer">Canonical</a> consolidates duplicate or very similar content and is not an indexing block. noindex excludes a page from the index when Google can fetch the signal. robots.txt controls crawling instead; a blocked page cannot deliver its noindex. Products must also remain discoverable through allowed categories.</p>
</div>
Sources
- Google: Faceted Navigation — Stand: 06.11.2026.
- Google: Canonical — Stand: 06.11.2026.
- Google: noindex — Stand: 06.11.2026.
- Google: Pagination — Stand: 06.11.2026.
- Google: Crawlable Links — Stand: 06.11.2026.
SEO & content for your business?
I deliver this for small and mid-sized businesses: at a fixed price agreed upfront, working directly with the person who builds it. Process, scope and pricing are on the service page.
See service & pricing Or request a free intro call